In December 2019, we stopped fighting as a standalone company and started seeking an acquirer [1]. The response we received was overwhelming but we were not successful.
This post-mortem is my way of saying thanks to so many people who helped us along the way. It also helps María and I close a chapter before we start the next one.
Here’s what happened.
What we built: A Virtual Closet app, on top of a learning model
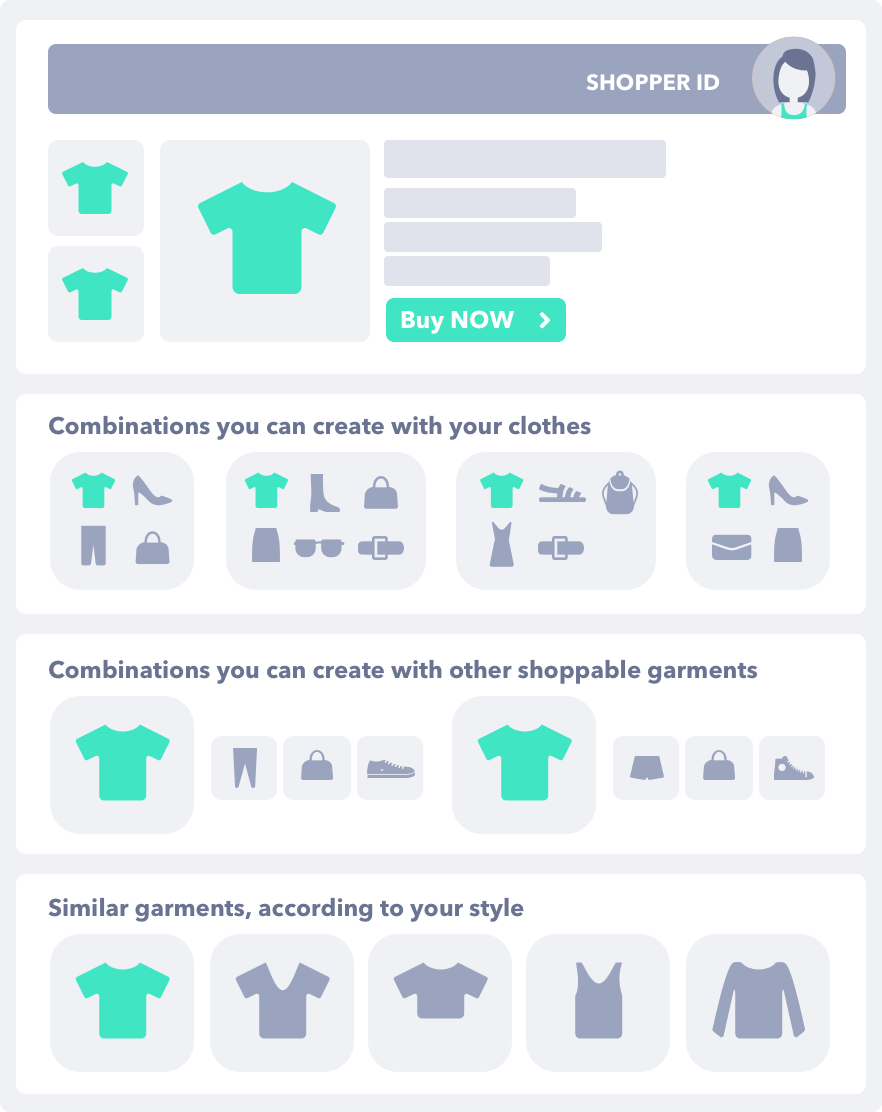
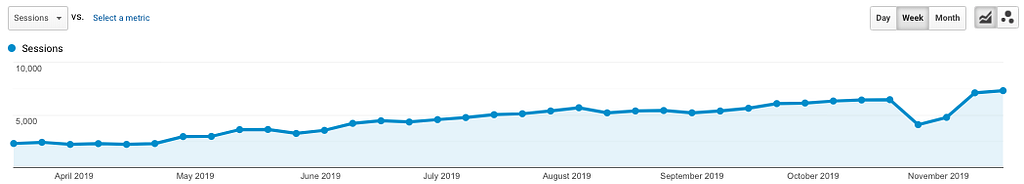
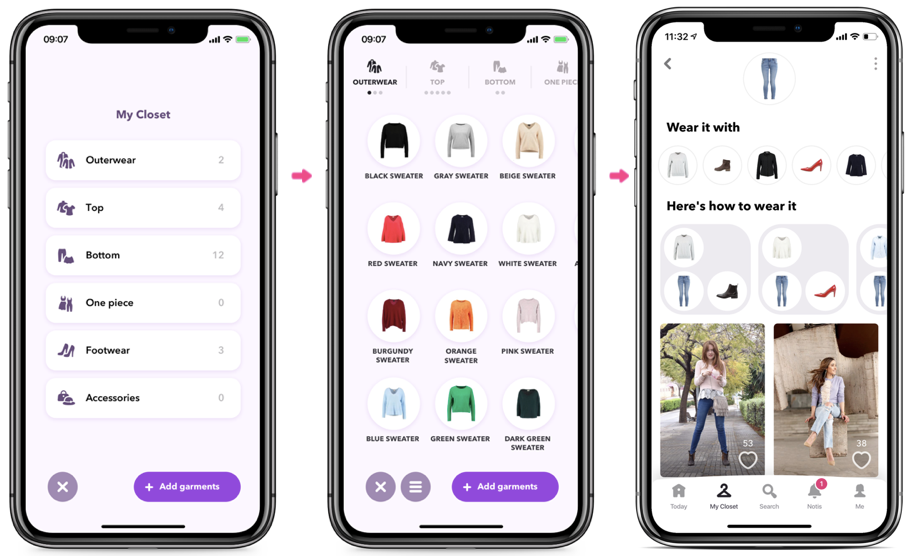
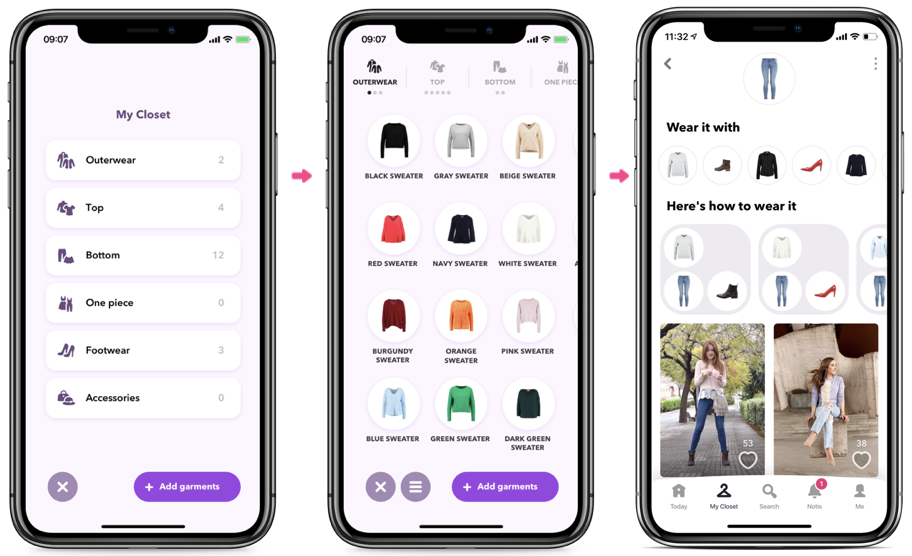
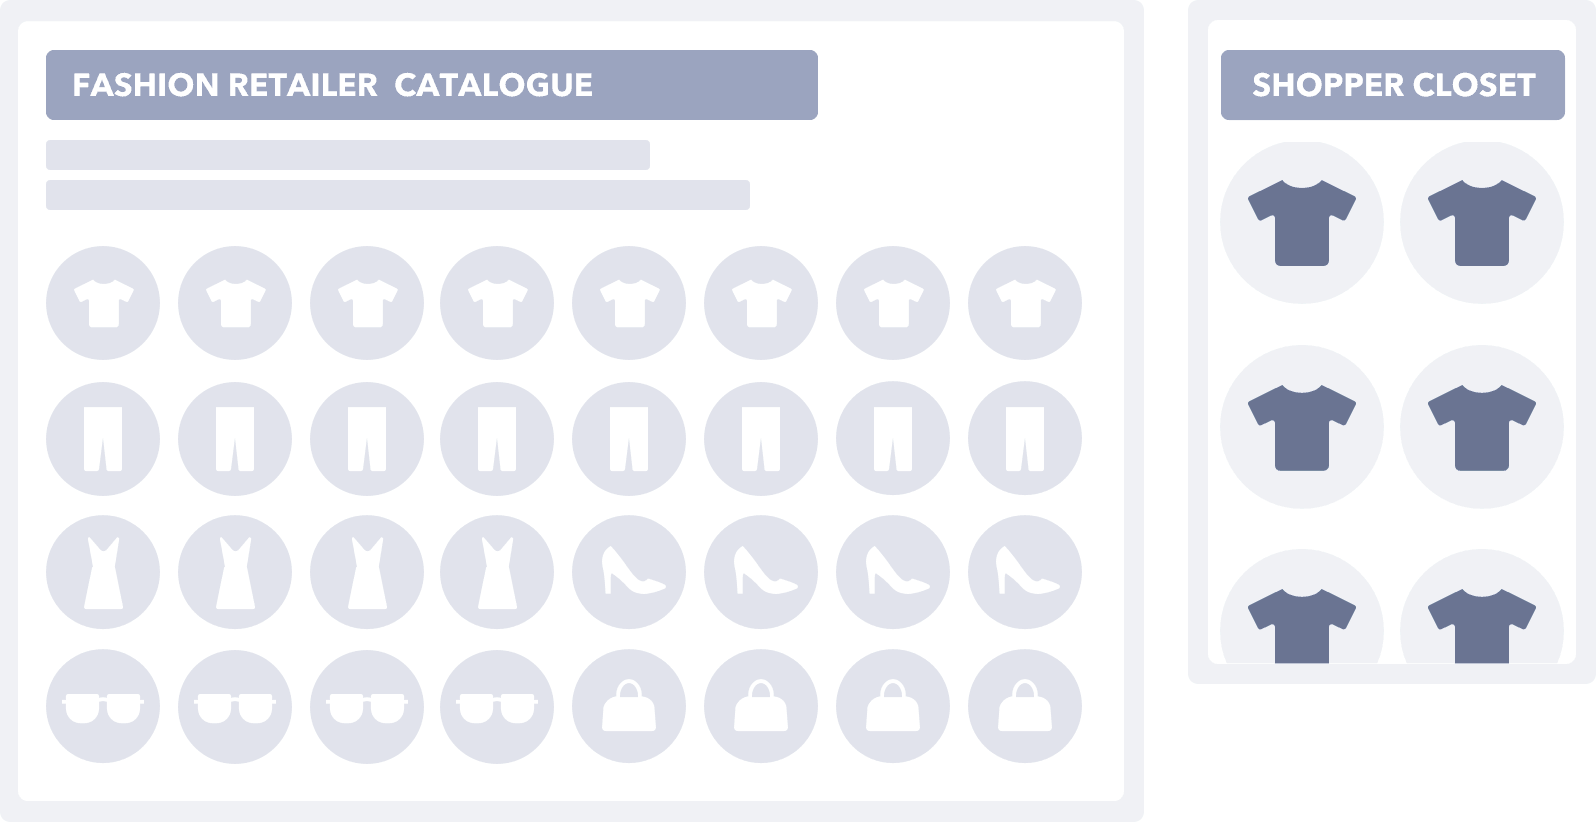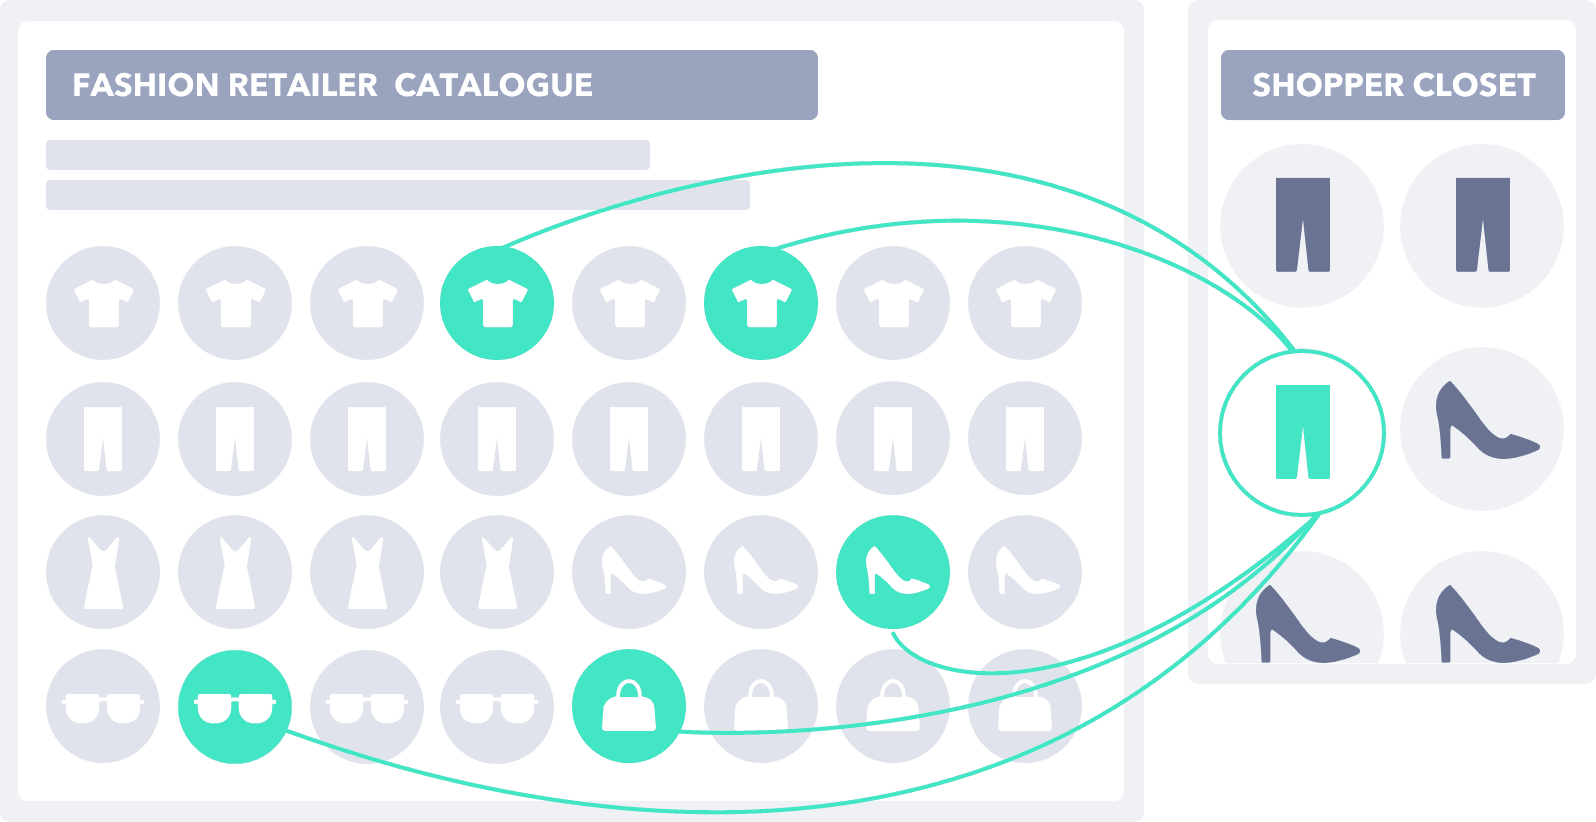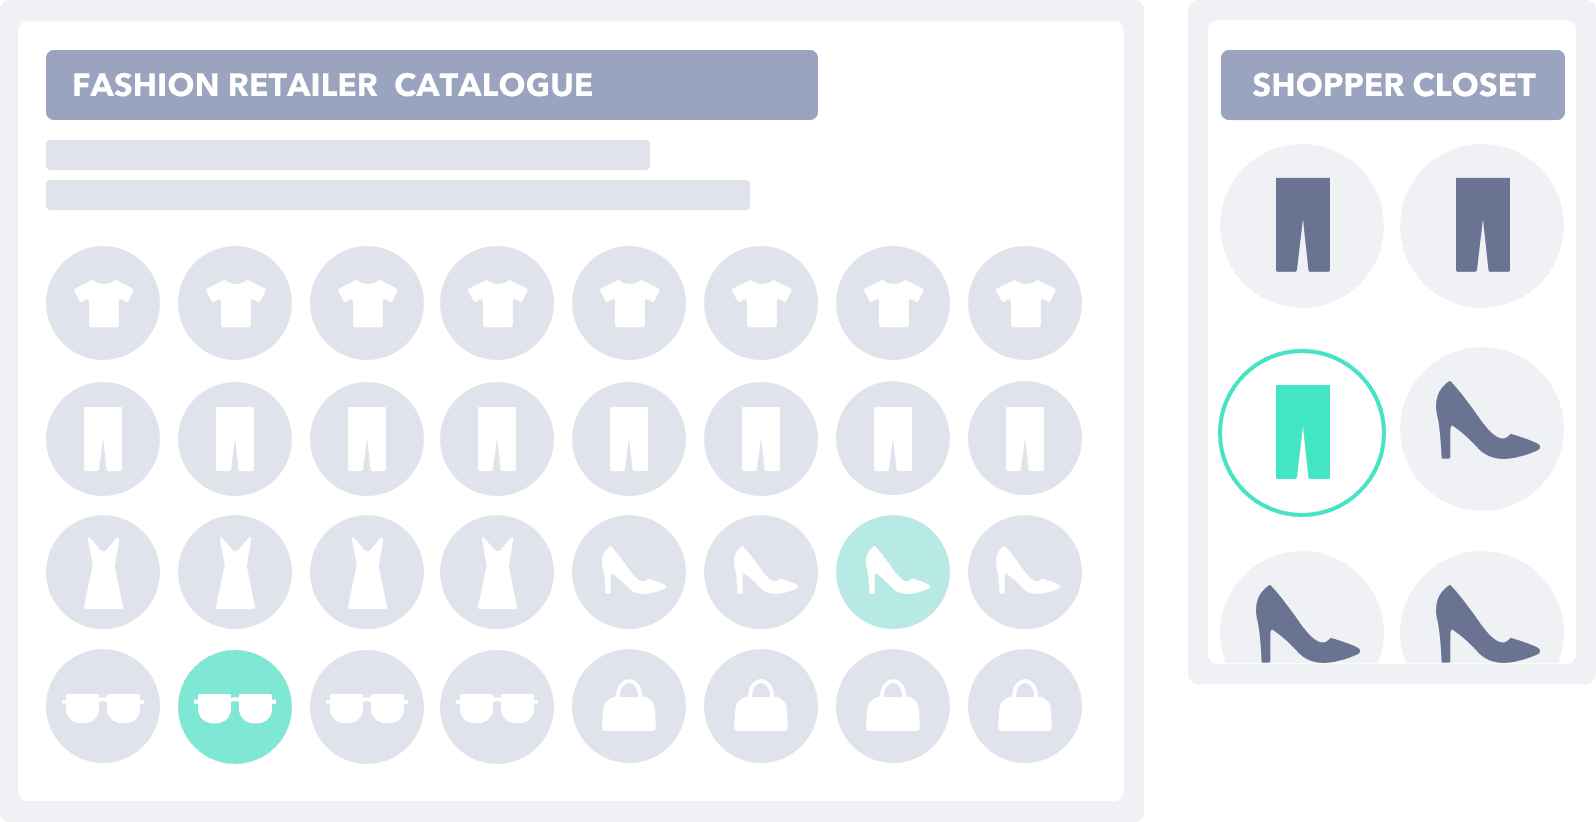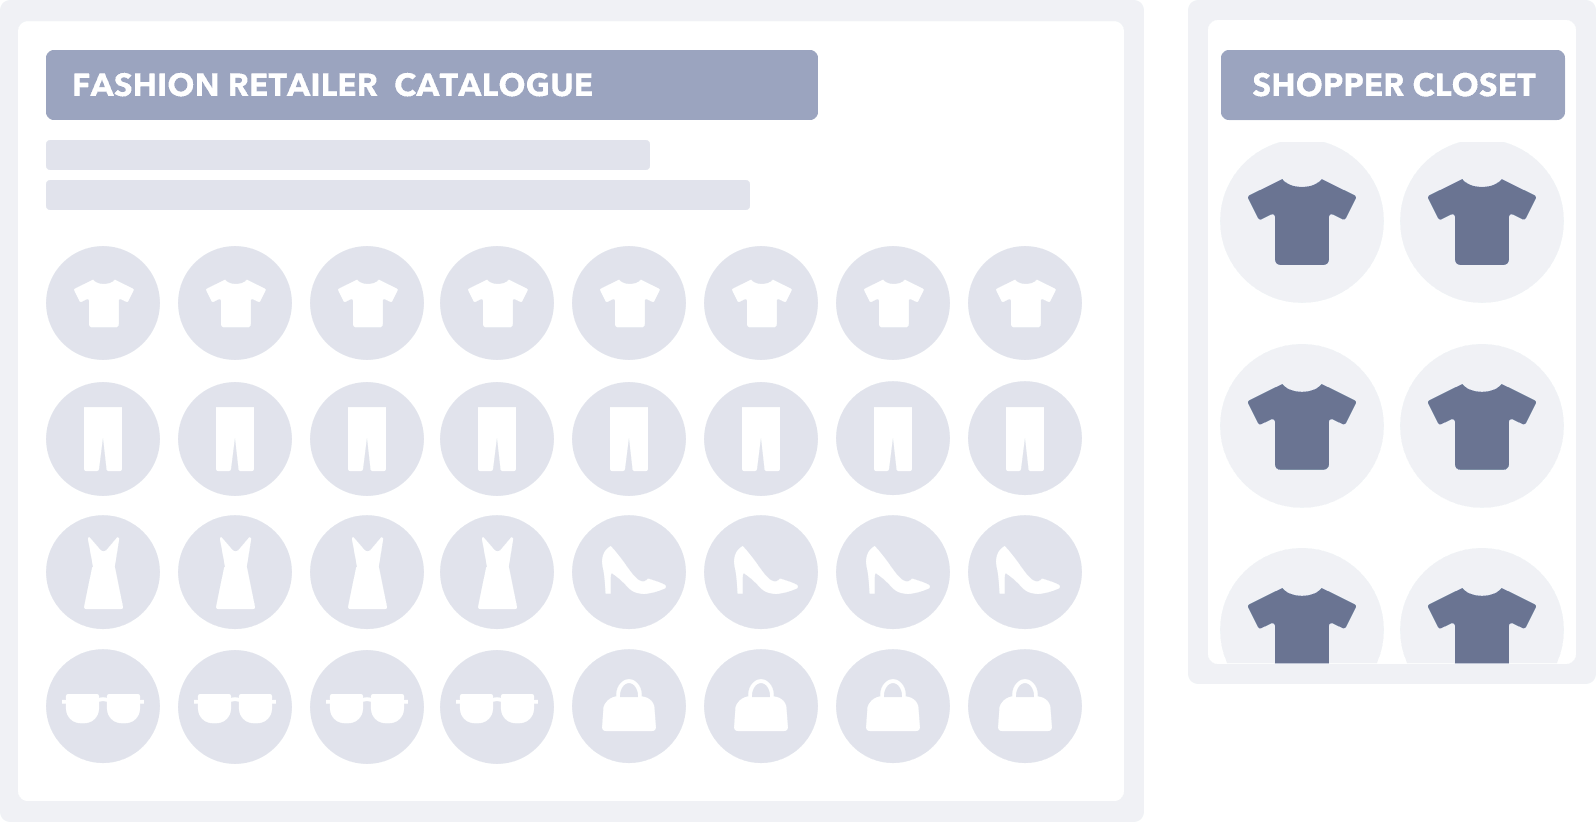
We’ve built a virtual closet app that allows women to easily digitize most of their clothes in less than 2 minutes. Then, the closet tells you how to combine your clothes: (i) it gives outfit suggestions, and (ii) it shows how other real women wear your same clothes. We had 5M installs, ~95% of them non-paid, good retention [2].
This is built on top of a learning model that automatically classifies clothes and understands people’s taste, by learning from users’ closet & outfit data, their queries and interactions. The result is a taste graph automating input classification & the delivery of suggestions. You can read about our tech assets at the end of this post [3].
While we were building the core of our tech, I failed at finding a successful business model. We tried different forms of monetization, mostly affiliation and subscription. I spoke with most fashion apps out there, and all had the same problem. And I ignored the second hand market, which turned out to be the good one.
Chicisimo App. More videos at the end of this post.
The M&A process
During Q4 2019 and Q1 2020, we had quality conversations with many tech players. We spoke with the product, tech and M&A teams with specific interest in Chicisimo. We knew some of those players from long.
However, I didn’t find an acquirer. Some tech players had started building similar learning models not long ago, others thought they could build the models themselves… I simply failed at generating excitement and urgency.
Three thoughts:
(i) There was a desire to hire the team because we built a fantastic team [4], but not to acquire the company;
(ii) There was a strong interest in our learning model, but the specifics of how we delivered the experience was irrelevant to most;
and (iii) There are several players considering building digital closets or automated style assistants. But not in the short term.
Failing is ok. Failing is not OK
When María and I started the company, we knew the enormous risk we were taking with our approach. We all knew that we could fail, and that was ok.
But failing is not ok. It is extremely hard. It comes slow and then super fast. Failing is personal. It comes with lots of nights without sleep and dealing with your physco is hard.
Sadly, failing affects other people and generates stress in those who most care about you.
A support network
Luckily, we have a strong support network who takes care of us. Investors, teammates, fellow entrepreneurs, friends and family. This network allowed us to never feel alone and to connect with almost anyone we’ve needed. And to share problems-questions-opportunities with fellow entrepreneurs who’ve gone thru similar situations.
One advice I’d give to entrepreneurs: surround yourself with people who will be well-balanced in the hard times, and connect with other entrepreneurs who’ll understand what you are going thru.
We’ve been lucky to have Iñaki Arrola with us, always setting an example. We’ve loved working with a fantastic team (Pedro, Juan, Saul, Mireia, Miguel, Goi) who was extremely successful at building what they were asked to build. Thanks also to Diego, Rafa, Álvaro, Micah and to so many others. María and I dreamed of giving you a different outcome, but it hasn’t been possible.
And to my cofounder María… sorry for the hard times, thank you for not giving up. We are going to make it.
We are happy to help others
Having received so much help, we’d love to help others. We like consumer product teams (product+design+engineering) who ship fast, very focused iterations impacting specific growth levers, again and again and again. If you think we can help, ping me.
What is next?
2020 couldn’t have been more intense:
While all the above was happening with Chicisimo, CRIF acquired 100% of Strands, the company that a few of us started in 2004. At Strands, we started by logging people’s online music behaviour and in 2007 we pivoted to logging people’s credit card payments. With that pivot, we built a business;
I had a mountain accident in June. The recovery from this accident gave me the motivation to recover physically asap, which has helped me recover from Chicisimo ending;
As a result, July and September have been calm for us, and María and I have been able to rest. We feel strong, happy and hyper active. And we are actually very excited about what comes next! 🚀🚀🚀
Aprox 3% of clothes use this process to be added to the closet. Other approaches are way more convenient to users, and fast. Read about our Smart Virtual Closet technology.
Alexa SEO is the effort to increase the number of organic installs of your Alexa Skill, making it easy for the correct audience to find and enable your Skill.
In this post, I share both basic and advanced Alexa SEO techniques to increase the number of organic installs of your Alexa Skill. This post was originally meant to be kept internal to our startup (Chicisimo), but then we thought it could be very helpful to some teams out there looking for non-paid acquisition.
At Chicisimo, we discovered that our learning method for ASO growth can be successfully applied to Alexa SEO (also known as Alexa Skills Store Optimization). At Chicisimo, most of our 5 millions iOS and Android installs come from ASO (or word of mouth from people who found us via ASO).
My name is Gabi and I am the co-founder of Chicisimo (Fashion Taste API).
Sadly, I’m here to communicate that we’ve decided to stop fighting as a standalone company, and we offer ourselves for sale. We’ve run out of cash. For the many people who’ve been supporting us, thanks so much for being there.
Today, we start a different fight: we are going to reach out to potential acquirers. The first step is to share our vision as loudly as possible, describing our assets and our team. Because we still believe.
We’ve converted a human problem into a computational problem
In the last 3 years, we’ve built a taste graph that classifies clothes and understands people’s taste. We have built a:
(ii) Key tech assets and products that you’ll see below. We’ve converted a human problem (understanding fashion taste) into a computational problem. This has been our focus from day 1, because understanding taste automatically, and being able to act upon it, will be the single biggest breakthrough in fashion ecommerce, we believe.
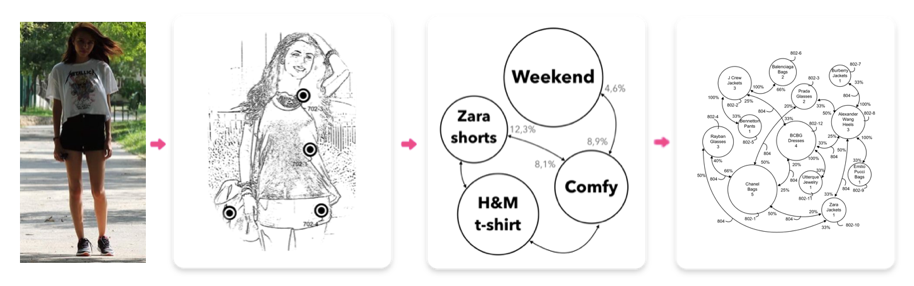
One of our processes.
What’s our situation?
For years, we’ve been pivoting to solve the above problem. We finally found the right path 36 months ago, but we haven’t found a relevant business model. We provide more details below. We started applying our technology to our own consumer products under the Chicisimo brand (see videos below), and we just very very recently started offering it as a SaaS via the Fashion Taste API with a strong business model. We’ve raised $3,5M (we are extremely thankful to our investors).
If you continue reading, I believe you’ll find an interesting product, market and team. At least, different from other approaches. I would really like to hear your thoughts after you read all this.
How should we proceed?
We’ve been wondering what to do under our situation and we don’t think there is a perfect way to proceed. We do know we can be a great fit for other players, so we are going to push as hard as we can:
Most importantly, with this post we want to publicly share our vision as loudly as possible. The best way to do it is to describe our assets and our team: our assets are a reflection of what we’ve considered truly important in fashion ecommerce.
Any other ideas? This is important for us.
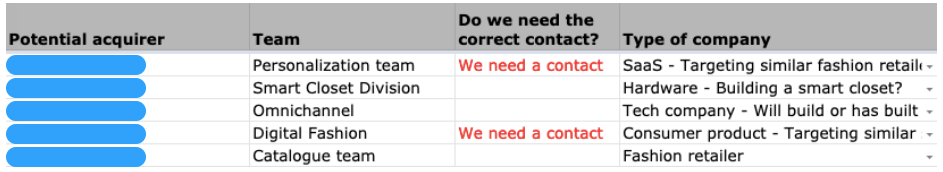
The list of teams we are contacting or want to contact
In-bedroom ecommerce, as an example
Saying that we build tech that “classifies clothes and understands taste” might seem a bit abstract. One of our consumer products is an example of how the tech is delivered to the end consumer. It’s an In-Bedroom Fashion Stylist that understands the user and her taste and knows what clothes she has in her closet. We strongly believe in in-bedroom ecommerce. It is actually the first time we publicly talk about this product.
#1 Asset: our fashion ontology
Ontology of fashion products. Because fashion lacks a standard to classify clothes.
Fashion lacks a standard to classify clothes or to refer to the variety of concepts that describe products, styles, and personal fashion preferences. When we found ourselves receiving millions of outfits, clothes, queries and related input, we only saw unorganized data, so chaotic that it was impossible to understand, manage or build on top of it. Our users could not really express their needs precisely, we could not describe our content in a way that could be found by those in need of it, we couldn’t even do a good job at categorizing our own content.
The situation above was the origin of our ontology. Today, our ontology understands any incoming input, cleans and structures incoming data, and converts unorganized data into data that a machine can perfectly work with.
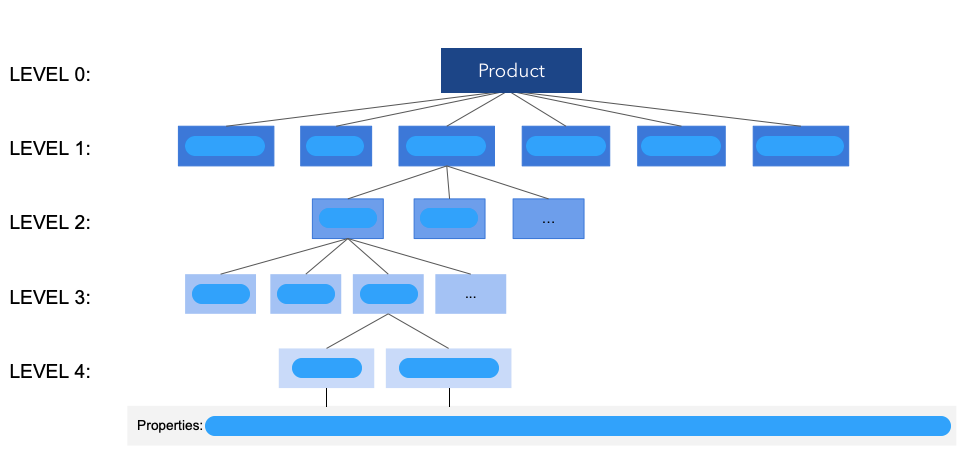
We consider our fashion ontology as the backbone of our Taste Graph technology. We divide our ontology into two parts:
Products ontology. It is a 5-level ontology that describes products and subjective characteristics of products;
Outfits ontology. It is a 2-level ontology that describes outfits, mostly with subjective descriptors.
#2 Asset: a system to classify clothes automatically, with 175 million classified and correlated meta-products
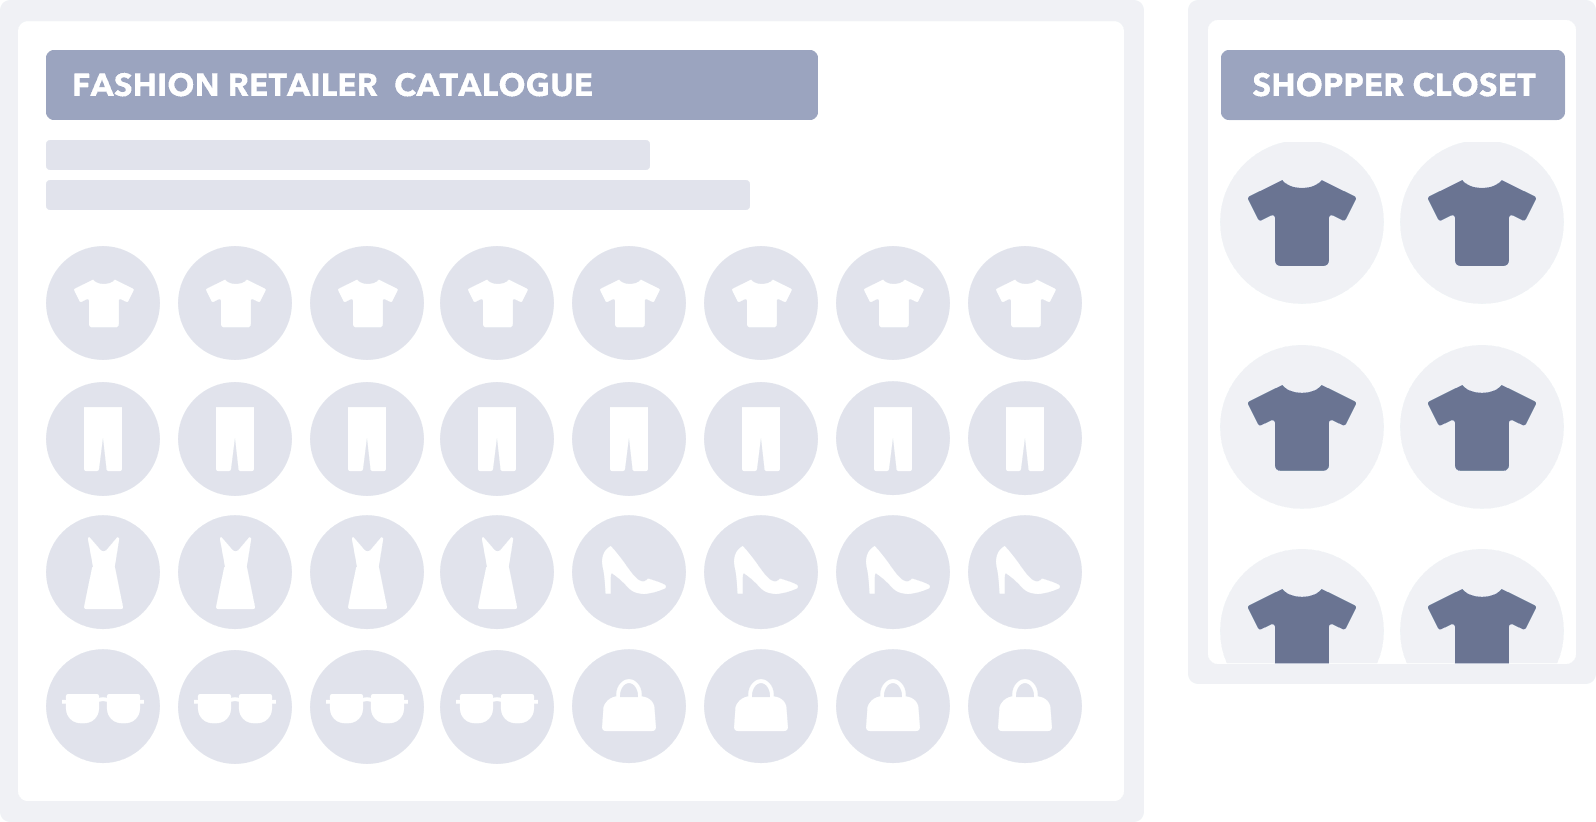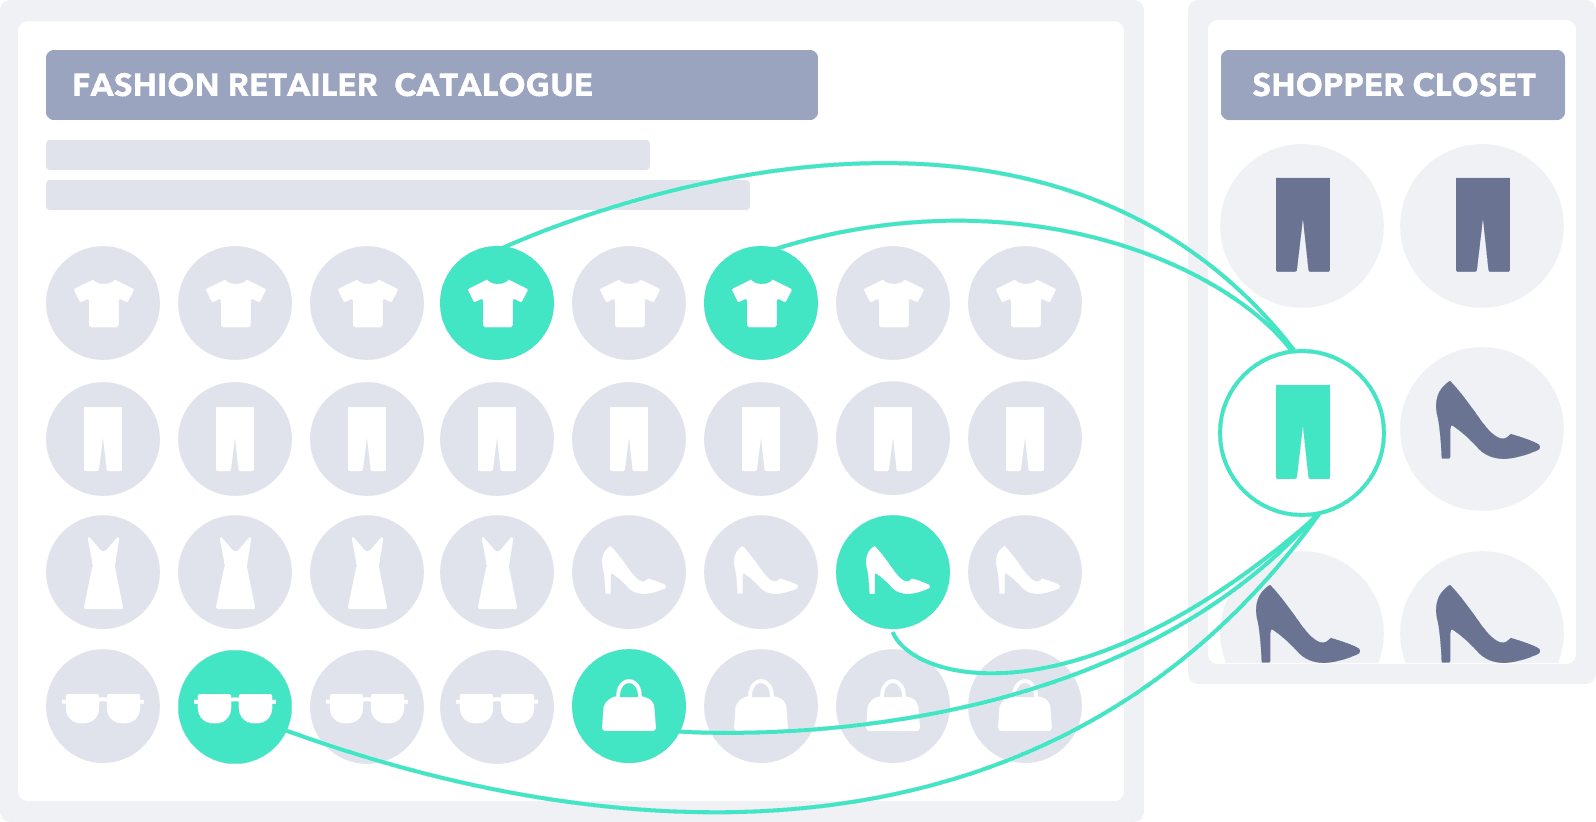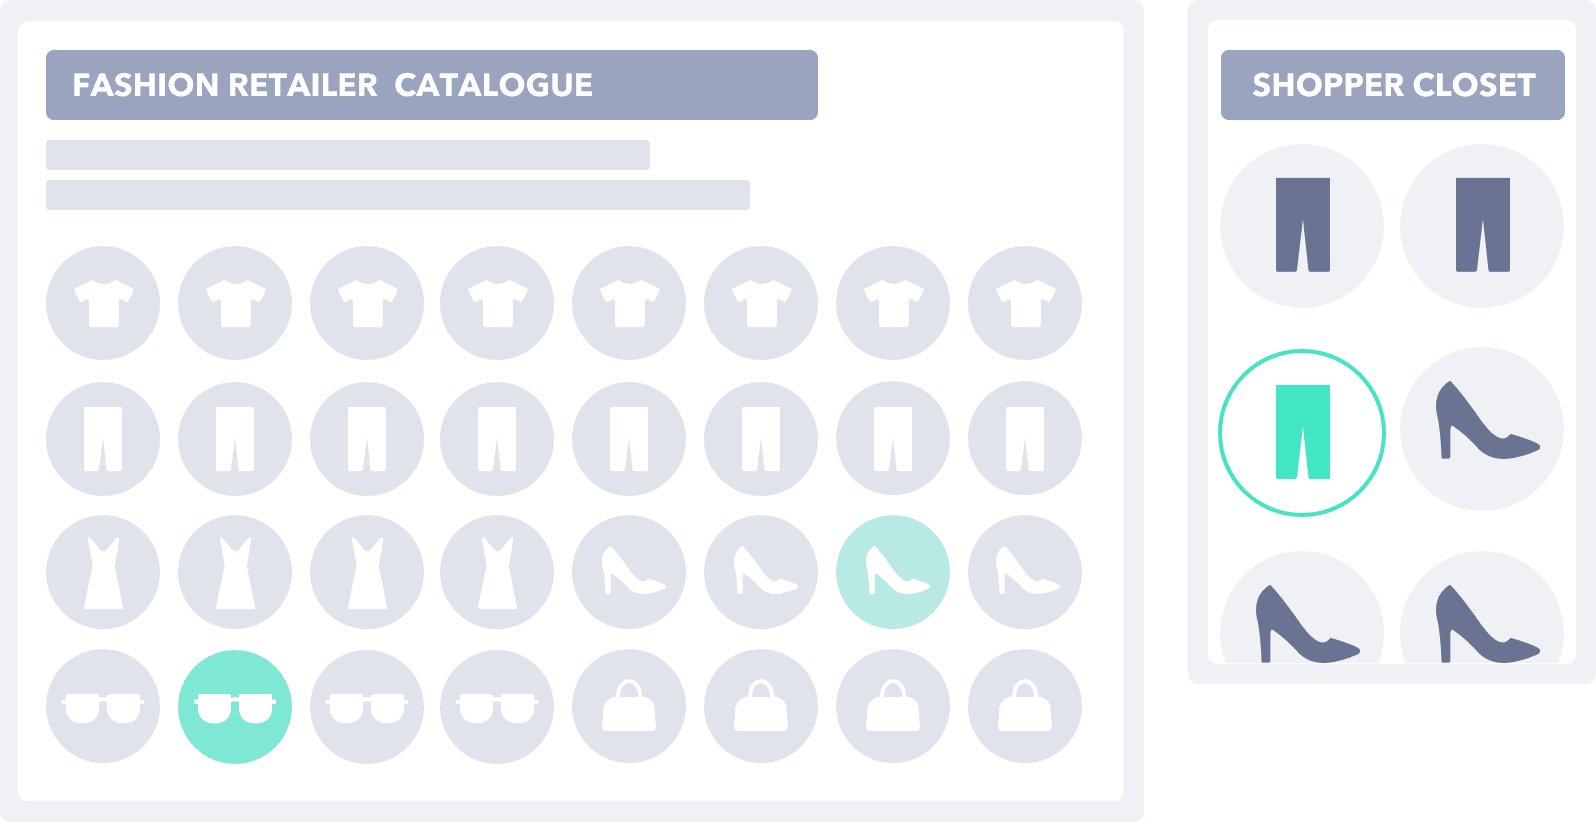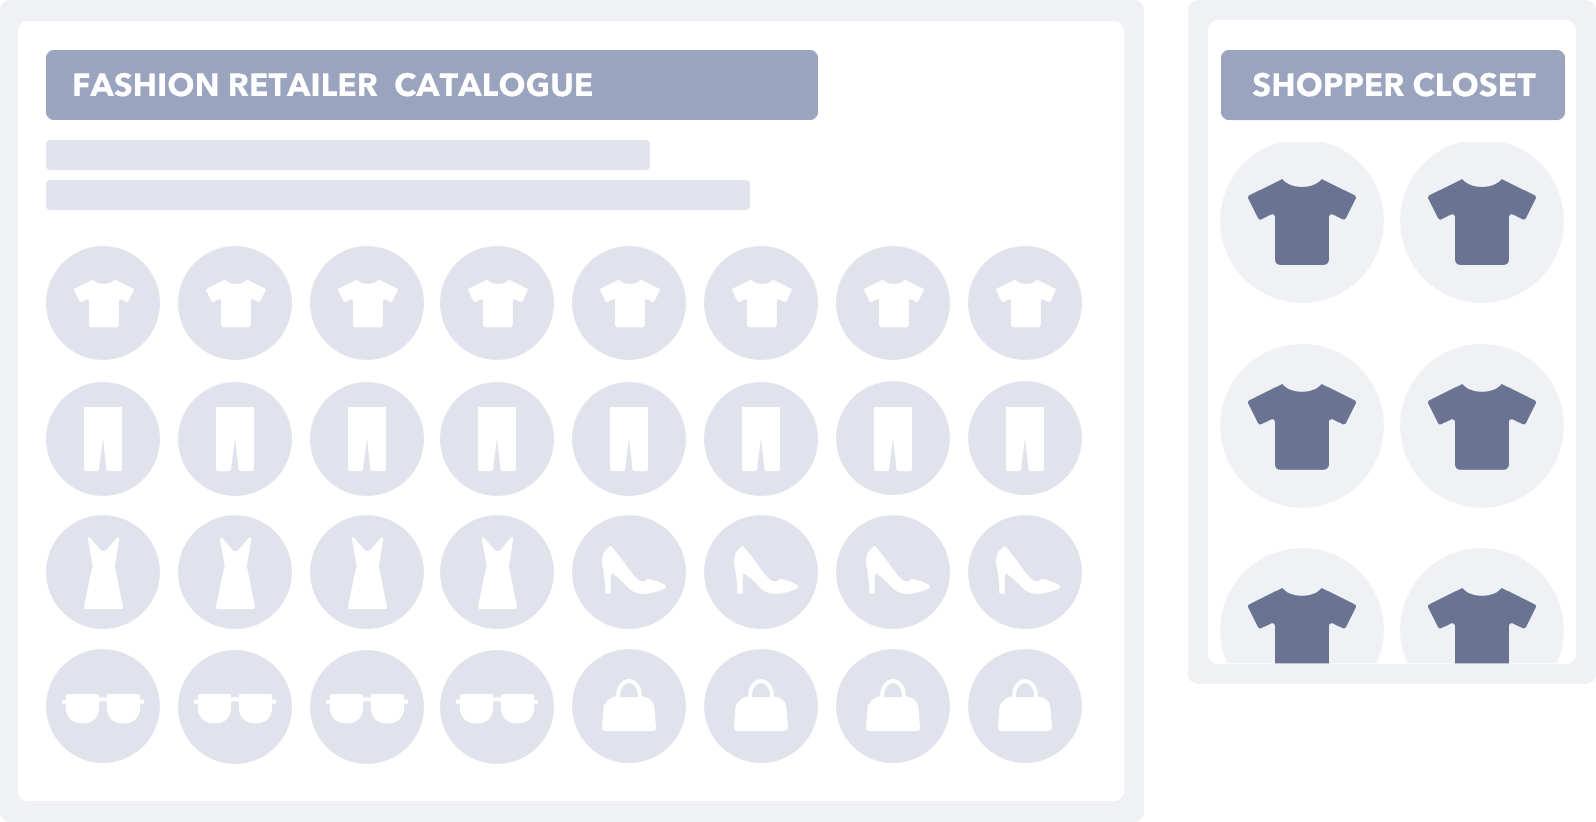
This system allows us to automatically understand, manage and act upon any collection from any retailer: similarities, correlations, recommendations.
This is the key asset that we have built. If we were to start from zero, this is the asset we’d need. It will allow any acquirer to be 2–3 years ahead of the rest.
To explain it easily, this system is like a brain that understands clothes and outfits, and allows you to organize and display products at your convenience, or your shopper’s convenience. It was constructed after analyzing millions of perfectly described outfits and fashion products uploaded to our system by different subsets of users of Chicisimo, and after analyzing how people interact with them.
The system converts fashion products into meta-products, which are abstractions of specific products of any catalog or closet. A fashion product is ephemeral, but its descriptors are not, so the system retains the value.
A meta-product is the most basic yet relevant description of a product, and one of the first tasks of our infrastructure is to convert any incoming fashion product into a meta-product. While a person might see a given garment, our system reads a set of descriptors, for example: burgundy + sweater + v-neck + comfy + casual + for school + size 42 + cashmere.
For any given retailer, this system can automatically digest its catalogue and then, automatically: (i) understand each product; (ii) identify missing information; (iii) identify similar products, defining similarity in a number of ways; (iv) build complete looks mixing and matching the clothes in the collection; (v) identify products that make sense to display together; (vi) recreate any outfit with garments of the catalogue; (vii) display the correct products for each shopper, or for the current interest of each shopper; (viii) if the system detects a product that it cannot understand, it isolates the descriptor and incorporates it into the ontology if the team so wishes.
A system to classify clothes automatically.
#3 Asset: a system to understand people, that builds a Taste Profile of each shopper
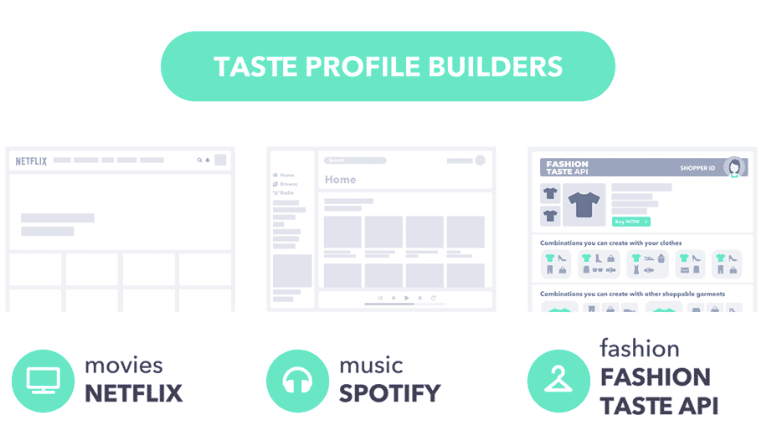
It is fascinating how easy it is to understand people, once you come up with the right approach, and you have the two assets above. Our approach is similar to what Spotify or Netflix do. Luckily for Spotify, music has a universally accepted classification system. Netflix simply did an exceptional job at building their classification system.
In our system, any action performed by the shopper implies an interaction with products or with sections of a channel. As the products and channel sections are perfectly described and structured, user interaction generates precise information about your shopper. This information is registered and organized, creating the shopper taste profile.
Creating taste profiles, the retailer understands each shopper, and can automatically adapt the shopper experience to her taste and needs in infinite ways.
Spotify, Netflix and the Fashion Taste API. Companies building Taste Profiles.
#4 Asset: one Fashion Taste Graph for each retailer
The Fashion Taste Graph of a retailer is, again, a brain. Like the brain of the “Chief Stylist” who knows precisely each product and shopper and the retailer editorial line.
It’s created by capturing the relations among the retailer’s products (garments and outfits), shoppers’ behaviour and descriptors. It improves exponentially with any new data point that it captures. It learns from any new action. And is able to assign new descriptors to any product or people based on previous learnings. Any relevant customer interaction in the future, will be built on top of a Taste Graph.
Interestingly, lots of retailers rely on editorial teams to organize and display very large collections of products. These teams do not trust machines to do the job, and we understand the reasoning behind that. We think that they are producing a unique editorial intelligence that they are letting go, and it should be retained.
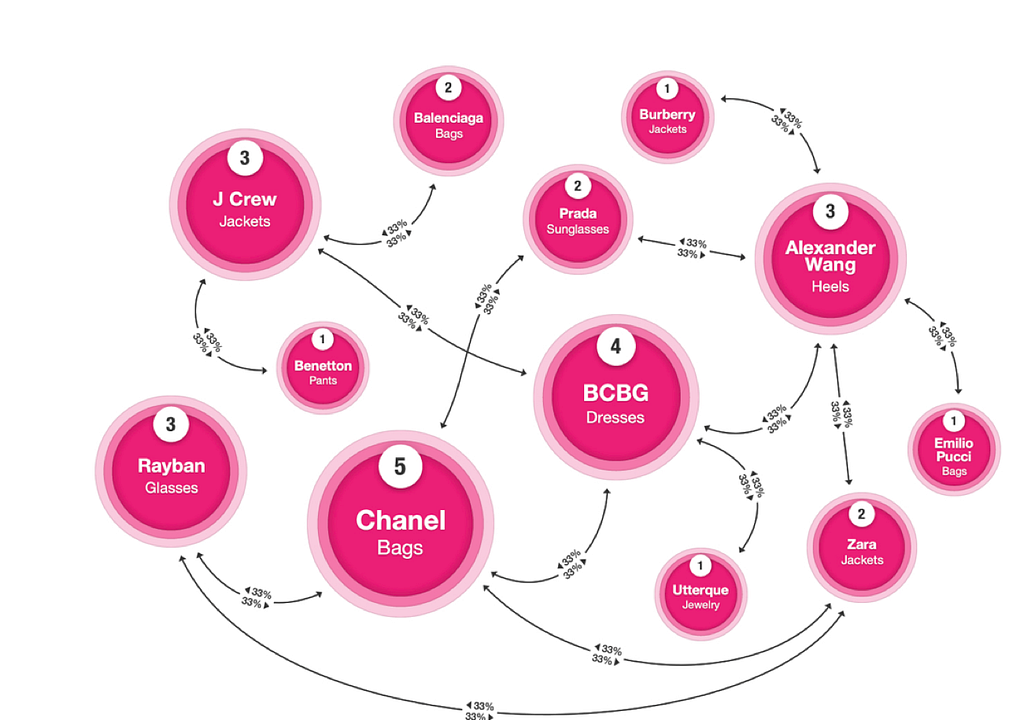
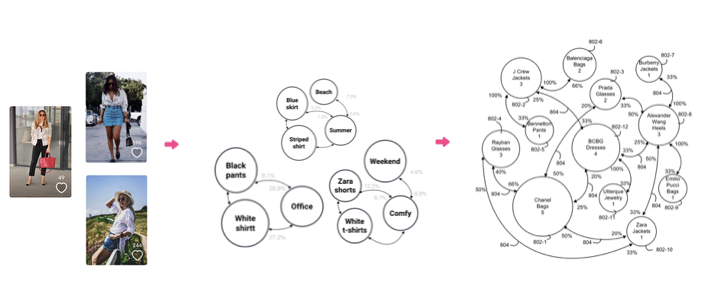
The first iterations of our Graph got the basic concepts right, but their understanding of shoppers and retailers was very poor. Above, a representation of our 2012 Taste Graph.
#5 Asset: our digital closet
Once you have the data architecture and the interfaces in place, a digital closet is a simple concept.
It comes a point in time when your impact as a team increases exponentially. In our case, that moment arrived when we started to have clean correlated data and we could operate it effectively. That’s the moment we are at: with the ability to build at exponential rates.
Our digital closet is an example of building on top of the right assets. Our Smart Virtual Closet Technology allows your shoppers to digitally store all their physical clothes, without any friction: the clothes they bought on your site, and the clothes they bought in other fashion retailers. It allows a retailer to help shoppers decide what to wear and what to buy, and it is really engaging.
We’ve obtained two key learnings:
From an architecture of information point of view, a person’s closet is exactly the same as the collection of any retailer. This realization had two major consequences for us: (i) we could remove a lot of code and we love that; and (ii) any work we do on fashion products is applicable both to a retailer collection and to a person’s closet;
Building digital closet tech requires interconnected efforts from very different disciplines. For example, it is fascinating how strong is the relation between the closet interfaces and the data architecture. Without the team structure we have, we couldn’t have built this tech.
A few applications: the In-Bedroom Fashion Stylist, built entirely on top of the above infrastructure and installable from the Alexa Skills Store; the mechanisms for adding clothes to your digital closet; the In-Store Outfit Recommender; the Digital Closet on iOS; and the Smart Fitting Room.
#6 Asset: two key patents. Why do we patent?
Chicisimo owns foundational patents in the online fashion market being infringed by one of the GAFA companies, and overcoming Facebook’s social graph.
Why? When we started looking into fashion taste, we considered that there were 3 processes we wanted to own: (i) mechanisms to capture taste inputs; (ii) systems to interpret input; and (iii) a system to automatically match an item in an image, against its equivalent in a database with ecommerce links to purchase that same product. We patented the second and third processes.
An independent review of Chicisimo’s portfolio uncovered market adoption related to linking user-submitted fashion images to shoppable items. Chicisimo’s patents are expected to provide a competitive advantage. We’ve also protected a taste graph based on correlations among fashion images (and inside of them), as opposed to Facebook’s social graph using similarities among users.
There is some controversy around patents, so I’ll clarify our position. First, we have a lot of experience in this field and this has absolutely never been a distraction in terms of time. Second, as a startup we need to create value and this method has proven successful in the past. Third, we’ve never thought of using patents against others. And now, our number one driver for building IP: companies sometimes need leverage to negotiate or deal with the big tech players. Even though a startup can’t get into an IP fight with a large company, our patents do provide and will provide that leverage.
#7 Asset: our SaaS to build one Taste Graph for each fashion retailer
Our SaaS solution, Fashion Taste API, is in its early days. It offers to build one Taste Graph to each retailer. We are in very specific conversations with some of the world’s largest fashion retailers to offer them our software as a service, and help them display their products to their shoppers.
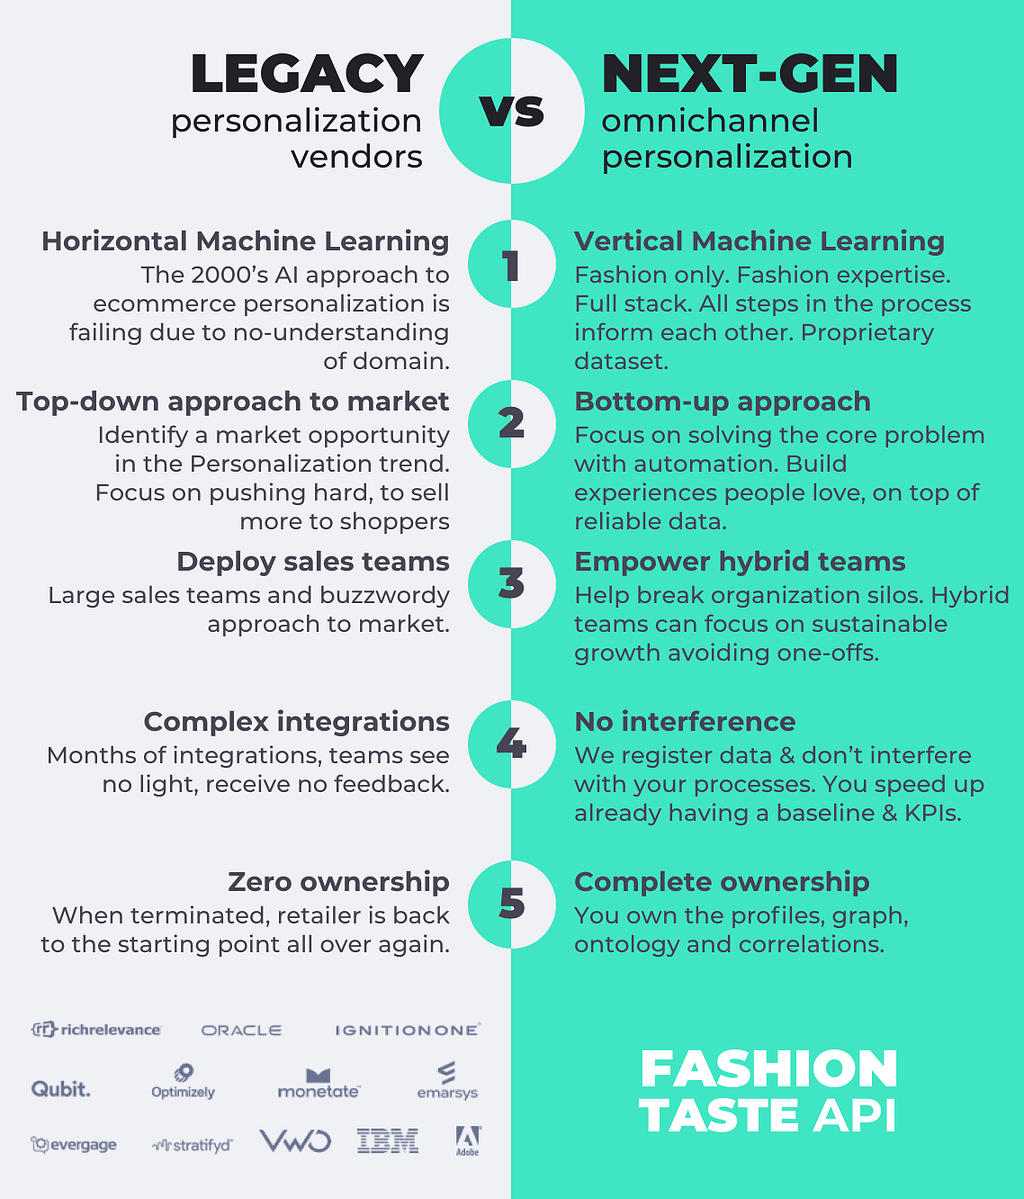
This is an interesting segment with an incorrect focus in my personal opinion. Most personalization players trying it in fashion are failing. The traditional approach focuses on capturing the relation among two nodes (i) without being able to understand the meaning of the node, and (ii) without being able to understand past purchase drivers of the shopper. In a world with ephemeral content and with no relevant ontology, this has proven not to work.
Our approach is different. Hopefully that’s been explained above.
Old vs new personalization approaches.
Team
We work exceptionally well together.
Without any doubt, this is obviously our key asset. An already built team with a production learning environment, tools, processes and clean data.
We are a team of 8. One person with long experience in automation and personalization, 1 robotics engineer specialized in fashion ontologies, 2 full-stack engineers, 1 iOS and 1 Android, 1 user-research and design, and 1 QA/product/community. Being a small team is a choice;
Being remote is a core part of our culture. Our main offices are located at Slack, GitHub and Whereby. We work exceptionally well together and are a bit obsessed with processes;
We absolutely love the problem and feel a strong respect for it. No one on earth knows more than us about the challenge of automating shopping and outfit advice;
The team has built and shipped the above infrastructure to production with an active community in search of fashion ideas, whose behaviour provides immediate feedback. We have an iOS app, an Alexa Skill, a Google Action and an Android app. We have received 376 messages per day from our community;
We have shipped an average of 3 releases per week considering no vacations. With an 8-person team doing all of the above, including one person devoted to iOS, we have built and shipped 204 different public releases to the App Store during 5.5 years and 919 pre-production releases;
Our internal data portal. Our job requires a team with complementary skills, and we initially had difficulties understanding each other. We solved this problem by creating an internal data portal that exposes all data and data relations. It is a key asset because it provides a shared language and knowledge where everyone in the team can easily access and see the same information.
From the corporate side, we are simple, clean and easy to evaluate. The company does not have tax or litigation issues, and does not lease any property. The company has not acquired, sold, merged, divested or reorganised. The company is incorporated in Spain, has no subsidiaries or holding companies, and owns assets in the US (intellectual property). It’s governed by a Board of Directors.
Miscellaneous
Some other interesting facts about our journey.
iOS subscriptions revenue
We tried to monetize in a number of ways, including a subscription service. Going this path actually means a lot of iterations and paying attention to issues different from the problem we are trying to solve. Although the revenue per install continues increasing, it’s not enough. This service will end up being free and the owner will benefit by gaining access to the attention, the closet data and the pocket of fashion shoppers.
We exposed our ontology to Google, and we ended up understanding the connection among SEO, conversational interfaces and ontologies
We are in no way an SEO company, but we’ve devoted some hours to exposing our ontology to Google and to building automatic sentences using different bags of descriptors. Simply by exposing this ontology, and with only one iteration, we multiplied by 3 our KPI (in this case, the KPI is unique mobile users coming from Google).
There is another aspect way more important: we’ve been able to understand how closely related SEO and rich snippets are to other areas that are very important for our segment: ontologies and conversational interfaces (Google Actions and Alexa Skills). Any work done in these aspects can have large impact on the others.
Exposing the ontology to Google. KPI: unique mobile users coming from Google.
Our iOS app: 3 releases each week during 5.5 years
With an 8-person team doing all of the above, including one person devoted to iOS, we have built and shipped 204 different public releases to the App Store during 5.5 years, plus 919 internal pre-production releases. That is an average of 3 releases per week considering no vacations;
Our rating has always been 5 stars or very close to it, depending on the country. However, it started to decline when we shipped our subscription service. We’ve been featured as App of the Day in 140 countries by Apple, many times. We’ve been rejected by the App Store many times for many reasons;
Even today’s version of the app is simply a step into its evolution.
376 messages per day from our community
Everything has its origin in understanding people. Even those assets apparently far apart from the user, such as the Taste Graph.
In these 5.5 years, we’ve received 752,000 messages from our community, an average of 376 messages a day. These messages responded to lots of different questions we had, or they were simply general feedback. We’ve done tons of user tests, built groups to test third-party apps during long periods of time, and more. The majority of the messages arrived via Intercom with 472,000 messages, Typeform with 14,600 messages, and via email most of the remaining ones;
We’ve identified retention levers and anti-levers using behavioral cohorts. We run cohorts not only over the actions that people performed, but also over the value they received. Time to convert has been critical for us. You can read about all this in How we grew from 0 to 4 million women on our fashion app;
“Chicisimo is like that friend or mother who helps you decide what to wear, when you have nothing to wear”, one person once told us. We couldn’t be prouder of really helping people.
Does a clothing purchase predict future clothing purchases?
Some people claim that purchasing a product does not always predict future purchases. We totally agree. You might buy today a pair of cowboy boots even if you’ve never seen a horse before. However, we are certain that past drivers of purchases do predict future purchases.
A Basque song
If you read all the way until the end, I appreciate it. In return, I want you to discover a song in a language you’ve probably never heard before: Basque. It has a strong meaning for me, and talks about letting go and about resistance. Txoria Txori.
Disclaimer: the above text should not be construed in any manner as acquisition or investment advice or a formal offer. Consult your advisers as to legal, business, and other matters concerning any acquisition of Chicisimo or its assets. Any texts or vision described above are for informational purposes only, and should not be relied upon when making any investment or acquisition decision.
Chicisimo announces today the “Fashion Taste API” to build a Taste Graph for each fashion retailer, and a Taste Profile of each fashion shopper. Read our Manifesto & Learn “Why Now?”
Fashion Taste API builds a Fashion Taste Graph for each fashion retailer, and a Taste Profile of each fashion shopper. It is the technology that will allow retailers to win the heart of people, their data and their pockets. It is the technology that is allowing Spotify, Netflix or Pinterest to understand each user and grow on top of that.
We’ve converted a human problem (understanding fashion taste) into a computational problem.
Our Manifesto
Technology is opening up lots of options for fashion and there are 4 elements that we consider true building blocks for the Future of Fashion Retail:
1. A TASTE GRAPH FOR EACH RETAILER
Each fashion retailer will own its Taste Graph like Pinterest does
The Taste Graph of a fashion retailer contains the intelligence generated by shoppers interactions with the retailer products and channels. Think of it as an intelligent data asset which value grows exponentially with any new event, and as an engine that allows you to manage and understand products and shoppers.
2. A TASTE PROFILE OF EACH SHOPPER
Retailers will build Taste Profiles of each shopper like Spotify or Netflix
A Taste Profile summarizes the taste of an individual shopper, what clothes she has in her closet, and what are the drivers behind her purchases.
3. AN ONTOLOGY INCLUSIVE OF ALL CONCEPTS
Ontologies will include all fashion concepts and the relations among them, even non-physical clothes descriptors but very relevant when deciding what to buy and why
Each retailer will manage its catalogue and its shoppers with their own ontology.
4. TOYS WILL WIN
Seemingly unimportant services that look like toys will win the heart of people, their data and their pockets.
Different teams have been trying to build such toys since the early 2000s. We believe there are a couple of organizations out there well positioned to make it. 3 examples we’ve built: the In-Store Outfit Recommender, the Digital Closet, and In-Bedroom Fashion Stylists, probably the most disruptive of all upcoming toys.
Why is *now* the right timing?
The fashion industry has come a long way since we patented our fashion taste graph in 2013: Machines can now understand fashion products AND fashion shoppers. A human problem (understanding fashion taste) is now a computational problem. This changes everything.
We can now control how to describe products and channels to maximize the information they provide about a shopper when she interacts with them. Also, we can add 3 times more descriptors per product thanks to the Taste Graph and the relations generated.
One of the roles of taste graphs is to assign descriptors to shoppers. Thanks to this automation, a fashion retailer can build a pretty accurate understanding of each shopper, with clean, structured and correlated shopper data.
Clean shopper data is the New Superpower of Product Teams. Fashion ontologies and Taste Graphs are now producing clean, structured and correlated taste data, at exponential rates.
Our background
We’ve created what-to-wear apps with the objective of learning how to understand taste automatically, so we can help people effectively. Via these apps, we have received millions of described outfits with described clothes, the described clothes in millions of closets, and hundreds of millions of what-to-wear queries from people trying to decide what to wear. Our infrastructure and learnings have been built on top of this data and the relations among the data.
The Next Generation of Personalization builds on top of taste understanding
If you are a large fashion retailer willing to improve how you manage and understand products and shoppers, please get in touch.
With this digital closet technology, women can easily recreate their physical closet, storing their clothes digitally. The closet then shows people how they can combine their clothes based on our analysis of millions of described outfits uploaded to our consumer apps, by real women. The closet also shows them how other people wear the clothes they have, or similar ones.
Bringing your clothes to your shopping experience
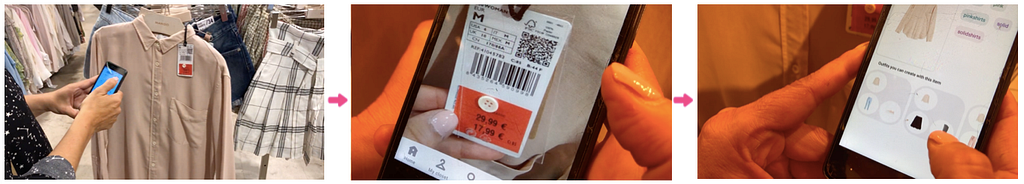
Today, we are introducing an in-store outfit recommender system. Built on top of the Fashion Taste API, it is based on a system to match a user’s clothes with any external garment regardless of the source.
In the video below, you can see my colleague Maria looking at clothes at a physical store, and how the Fashion Taste API recommends what outfits she can create with the clothes in her closet and the garment she is about to buy.
This is the process: We are reading the QR, extracting the images, and sending an image to our system where a deep learning algorithm extracts descriptors of the garment. Think of these descriptors as a “bag of descriptors”. This bag of descriptors is then sent to our taste graph which tells us how it correlates with the clothes in the user’s closet.
An ontology and a taste graph to enable automation of outfit advice
The asset that allows us to interpret any incoming garment is our ontology. It also works with outfits and text.
The Fashion Taste API ontology is the classification of descriptors needed to define an outfit, in the terms that are relevant for women, speaking the vocabulary they use. We’ve created this ontology through the analysis of how women search for outfits, how they tag them, and how they classify them.
(Among other things) Our ontology allows us to convert any garment into “metagarments”. Metagarments are the most basic yet relevant description of garments (like bags of descriptors), and they allow our system and algorithms to have a clear understanding of 100% of incoming garments. It is this understanding what allows the taste graph to be effective at doing its job, and match the garment with other garments. As we know what garments people have in their closet, we filter by those, and return a complete outfit. With this, building a personalization platform for fashion retail is a reality.
We see this infrastructure applied to fitting rooms, smart mirrors in our bedrooms, and while shopping online. The learning here is that, while clothes are chaotic from the point of view of classification and capturing, there is a way to automatically bring clean, structured data to clothes and fashion taste. This changes everything, because it’s a new beginning.
Outfits provide a unique perspective into taste
We’ve been working on recommender systems since 2004 in different verticals. In fashion, the challenge we found interesting is how to capture the data and then discern the underlying taste. Our thesis is that online fashion will be transformed by a tool that understands taste. Because if you understand taste, you can delight people.
“Outfits” are the asset that allows taste to be understood. They bring the context that lead people to describe their clothes, their what-to-wear needs, and other relevant taste descriptors.
While the traditional approach to recommender systems for fashion focus on suggesting you more products to buy without understanding your taste, we believe that the focus should be different. And that’s our focus: understanding people at an individual level: their needs, behaviour and taste.
How do people describe their clothes and outfits? What clothes do they have in their closets?A taste graph to understand fashion tasteA user’s digital closet powered by the Fashion Taste API
The future of fashion looks outstanding: new hardware, new sources of input, a better understanding of people
The future of fashion looks outstanding, we believe. Each of us will have our own automated personal stylist, accessible both via a mobile app and via a piece of hardware in our bedroom. This system will store our clothes and our behaviour, originated from sources of input with little friction.
Based on this understanding, this personal stylist will help us feel well and confident with our outfits and ourselves. That’s the objective.
There is plenty of data in the manufacturing and distribution of clothes. But once clothes are sold and people are wearing them, there is nothing. We simply can’t access people’s closets or understand their outfits.
In the following lines, I will share the following:
Taste graphs will transform fashion;
They will focus on understanding post-purchase clothing behaviour;
They will allow tech companies to understand taste, as Spotify does with music;
They will end up owning people’s attention, because they will be useful.
Analyzing demand for outfits
The learnings below are based on 4 years analyzing the demand of outfit ideas. Analyzing millions of described outfits, the described clothes in millions of closets, and the what-to-wear queries from people trying to decide what to wear for any occasion you can think of.
We’ve focused on two questions: How do people describe their clothes, outfits and what-to-wear needs? How can we learn about what clothes people have in their closets? In order to respond to these questions, we built the Fashion Taste API, an open API that helps fashion retailers understand the taste of each individual shopper and offer a personalized omnichannel fashion experience.
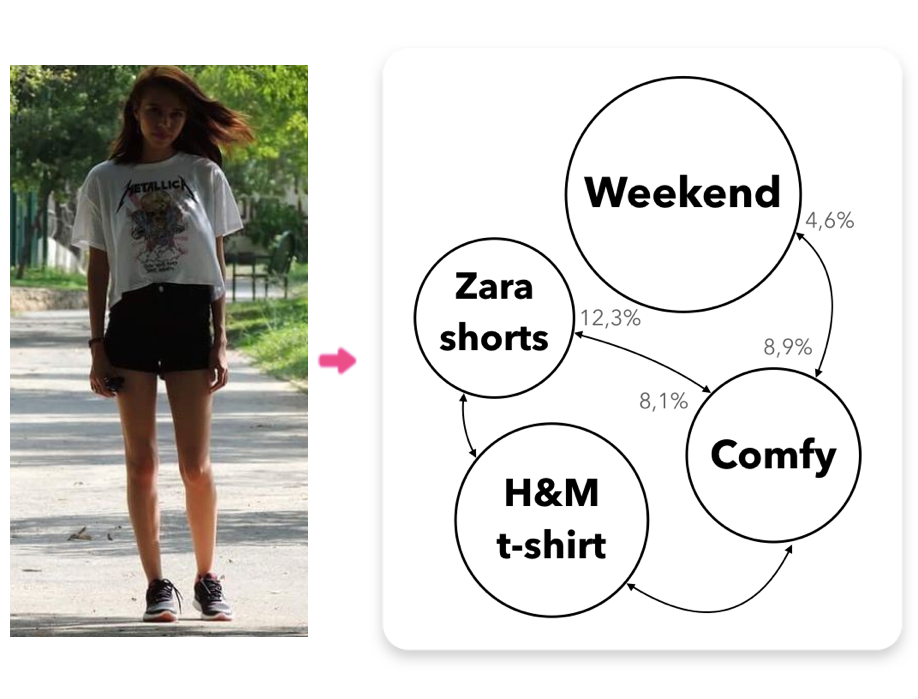
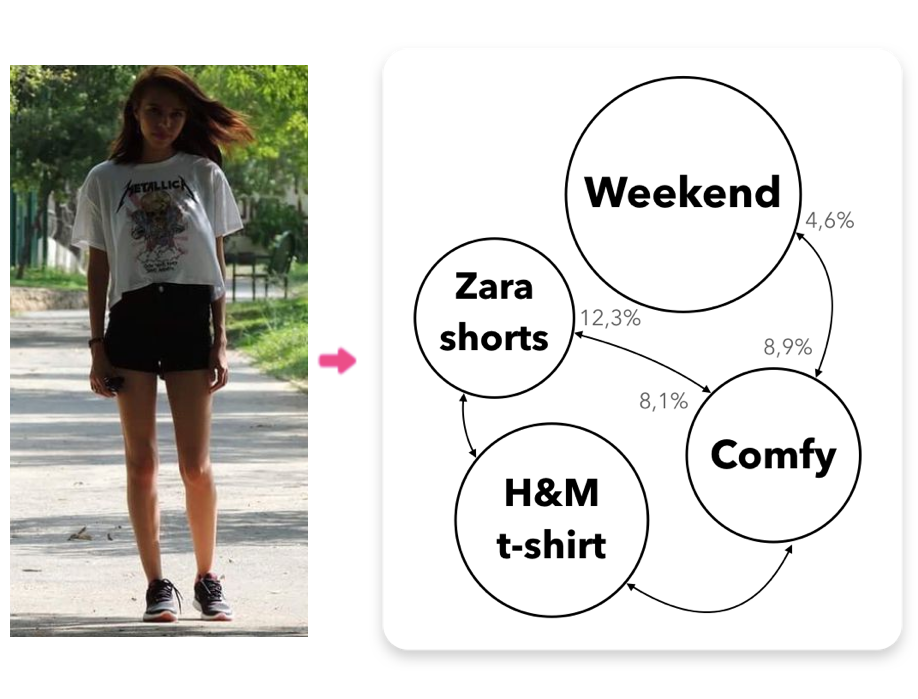
An outfit is a playlist of clothes but at the same time is much more. It is also a correlated list of descriptors: it can be comfy, or perfect for the weekend. An outfit contains correlations among clothes, and more important, the deep meaning that a person assigns to her clothing preferences. Outfits provide a unique perspective into closets.
Taste graphs will allow teams to own people’s attention
The biggest opportunity in fashion technology today is to build memorable omni-channel experiences, on top of the fashion taste profile of each individual shopper. The objective of the Fashion Taste API is that fashion retailers can focus on the building side, while easily accessing the clean, structured and correlated taste of each shopper.
Traditional tech efforts focus on efficiently selling more clothes to people, without understanding the shopper interests or context. Once the purchase is finished, companies are blind and can’t see what happens next.
Offering a post-purchase experience that helps people feel well with their clothes, will let the winner own people’s attention, and so many more things as a result.
Taste graphs will power a Spotify for fashion
Spotify has a similar approach. After you listen to music in Spotify, they have a specific profile of you, with your expressed preferences. As you enjoy their services more and more, your taste profile gets better, and when they recommend you music, it’s like if they’d know you. Well, they do. The same is done by the Fashion Taste API.
Fashion taste graphs will help you decide what to wear at any time. You’ll be able to easily store your clothes in a virtual closet, and it will put outfits together for you. It will help you plan your outfits depending on your context, and will suggest new clothes that match your wardrobe.
Helping people feel well with their clothes will be the key functionality of such a service. People want to feel confident, comfortable, happy, beautiful, unique, sexy, stylish, powerful. Instead of that, many people feel stressed or bored or tiny. More than about clothes, it’s about wellness.
1. Capture units of taste data
Before we try to understand taste, we need to understand what type of data we need to focus on. Spotify focuses mostly on playcounts (each time you listen to a song), and a playcount clearly defines your current behaviour.
We have learnt that the units of capturable taste data are related to text and images. Words express a need (“i need ideas to go to the office”). Images of clothes represent the clothes people own, and need help with. There are other units of capturable taste data, but it comes down to text and images. Then, in our mobile app we’ve built different easy-to-use input interfaces to capture data and allow people to communicate with the system.
2. An ontology of what-to-wear needs
Fashion has a problem: it lacks a common classification system. The expression of clothing behaviour is very fragmented: text and images have different meanings for each person, and each person expresses the same concept differently. Due to the lack of this classification (or taxonomy), people’s data is noisy and algorithms cannot work with it. To solve this problem, we’ve built a fashion ontology, which is the backbone of our taste graph.
Our ontology has been built to understand how people refer to their what-to-wear needs and how they describe their outfits. We don’t think it is important to build a taxonomy that describes clothes (there are many teams doing so), so we don’t want to extract 100% of the metadata of a “blue and white striped cotton v-neck shirt with long sleeves”.
The objective of our ontology is to understand people, not to understand clothes. We want to help you decide “how to wear your black dress to go to your friend’s wedding during a cold day”. This ontology allows us to understand people, their behaviour and their needs, and also converts incoming data into clean and structured data, so our algorithms can make use of it.
3. Taste graphs to understand fashion taste
When we get dressed in the mornings, we establish correlations among clothes, and among our ways of describing our outfits and needs. It will become easier and easier for a machine to capture and correlate clothes in an outfit, but the real value is to capture correlations as described by people.
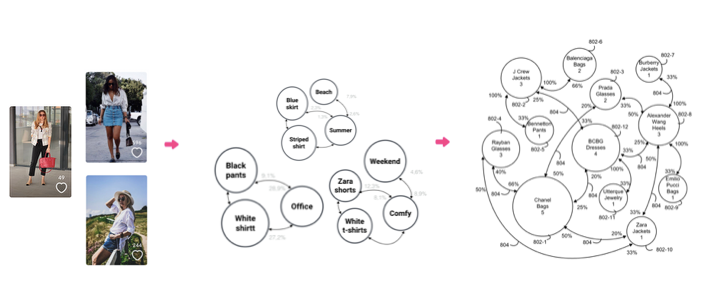
Taste graphs capture those correlations among descriptors, outfits and people. Think of it as a brain that understands “what goes well with” any garment for a particular occasion. It has this understanding because it analyzes hundreds of millions of correlated descriptors, described outfits and queries. Then, it filters them to your specific characteristics and context.
The end game
Taste graphs will provide structured and correlated taste data. And then will allow teams to build personalized omnichannel experiences for each customer. Our closets will be taste graphs connected to ecommerce catalogues (also graphs), and everything will change. Taste graphs will transform fashion.
Originally published on HackerNoon, January 2018. It was on the front page of Hacker News for almost an entire day.
Three years ago we launched Chicisimo, our goal was to offer automated outfit advice. Today, with over 4 million women on the app, we want to share how our data and machine learning approach helped us grow. It’s been chaotic but it is now under control.
Our thesis: outfits are the best asset to understand people’s taste. Understanding taste will transform online fashion
If we wanted to build a human-level tool to offer automated outfit advice, we needed to understand people’s fashion taste. A friend can give us outfit advice because after seeing what we normally wear, she’s learnt our style. How could we build a system that learns fashion taste?
We had previous experience with taste-based projects and a background in machine learning applied to music and other sectors. We saw how a collaborative filtering tool transformed the music industry from blindness to totally understanding people (check out the Audioscrobbler story). It also made life better for those who love music, and created several unicorns along the way.
With this background, we built the following thesis: online fashion will be transformed by a tool that understands taste. Because if you understand taste, you can delight people with relevant content and a meaningful experience. We also thought that outfits were the asset that would allow taste to be understood, to learn what people wear or have in their closet, and what style each of us likes.
Online fashion will be transformed by a tool that understands taste. Because if you understand taste, you can delight people. Outfits are the asset that allows taste to be understood.
Retention: what we learned
From previous experience building mobile products, even in Symbian back then, we knew it was easy to bring people to an app but difficult to retain them. So we focused on small iterations to learn as fast as possible.
We launched an extremely early alpha of Chicisimo with one key functionality. We launched under another name and in another country. You couldn’t even upload photos, but it allowed us to iterate with real data and get a lot of qualitative input. At some point, we launched the real Chicisimo, and removed this alpha from the App Store.
We spent a long time trying to understand what our true levers of retention were, and what algorithms we needed in order to match content and people.
Three things helped with retention:
(a) Identify retention levers using behavioral cohorts. We run cohorts not only over the actions that people performed, but also over the value they received. This was hard to conceptualize for an app such as Chicisimo. We thought in terms of what specific and measurable value people received, measured it, and ran cohorts over those events, and then we were able to iterate over value received, not only over actions people performed. We also defined and removed anti-levers, all those noisy things that distract from the main value, and got all the relevant metrics for different time periods: first session, first day, first week.
(b) Re-think the onboarding process, once we knew the levers of retention. We define it as the process by which new signups find the value of the app as soon as possible, and before we lose them. We clearly articulated to ourselves what needed to happen, what and when. It went something like this: if people don’t do [action] during their first 7 minutes in their first session, they will not come back. So we need to change the experience to make that happen. We also ran tons of user tests with different types of people, and observed how they perceived, or mostly didn’t, the retention lever.
(c) Define how we learn. The data approach described above is key, but there is much more than data when building a product people love. In our case, first of all, we think that the what-to-wear problem is a very important one to solve, and we truly respect it. We obsess over understanding the problem, and over understanding how our solution is helping, or not. It’s our way of showing respect.
This leads me to one of the most surprising aspects of building a product: the fact that, regularly, we access new corpuses of knowledge that we did not have before, which help us improve the product significantly. When we’ve obtained these game-changing learnings, it’s always been by focusing on two aspects: how people relate to the problem, and how people relate to the product. There are a million subtleties that happen in these two relations, and we are building Chicisimo by trying to understand them.
Talking with one of my colleagues, she once told me: “this is not about data, this is about people”. And the truth is, from day one we’ve learnt significantly by having conversations with women about how they relate with the problem, and with solutions. We use several mechanisms: face to face conversations, reading the emails we get from women without predefined questions, or asking for feedback around specific topics. And then we talk among ourselves and try to articulate the learnings.
At some point, we were lucky to get noticed by the App Store team, and we’ve been featured as App of the Day throughout the world.
The app got viewed by 957,437 uniques thanks to this feature, for a total of 1.3M times. In our case, app features have a 0.5% conversion rate from impression to app install; ASO has a 3% conversion, and referrers 45%.
Second step: building the data platform to learn people’s fashion needs
The app aims at understanding taste so we can do a better job at suggesting outfit ideas. The simple act of delivering the right content at the right time can absolutely wow people, although it is an extremely difficult utility to build.
Chicisimo content is 100% user-generated, and this poses some challenges: the system needs to classify different types of content automatically, build the right incentives, and understand how to match content and needs.
We soon saw that there was a lot of data coming in. After thinking “hey, how cool we are, look at all this data we have”, we realized it was actually a nightmare because, being chaotic, the data wasn’t actionable. This wasn’t cool at all. But then we decided to start giving some structure to parts of the data, and we ended up inventing what we called the Social Fashion Graph. The graph is a compact representation of how needs, outfits and people interrelate, a concept that helped us build the data platform.
We thought of outfits as playlists: an outfit is a combination of items that makes sense to consume together. Using collaborative filtering, the relations captured here allow us to offer recommendations in different areas of the app.
There was still a lot of noise in the data, and one of the hardest things was to understand how people were expressing the same fashion need in different ways, which made matching content and needs even more difficult. Lots of people might need ideas to go to school, and express that specific need in a hundred different ways. How do you capture this diversity, and how do you provide structure to it? We built a system to collect concepts, we call them needs, and captured equivalences among different ways to express them.
We now understand that an outfit, a need or a person can have a lot of understandable data attached, if you allow people to express freely (the app) while having the right system behind (the platform). Structuring data gave us control, while encouraging unstructured data gave us knowledge and flexibility.
The end result is our current system. A system that learns the meaning of an outfit, how to respond to a need, or the taste of an individual. And I wouldn’t even dare saying that this is Day 1 for us.
Each need has different data attached to it. It belongs to a certain category; it is correlated to other needs; it is attached to different types of outfits and shoppable products; it plays a certain role in the ontology.
The amount of work we have in front of us is immense, but we feel things are now under control. One of the new areas we’ve been working on is adding a fourth element to the Social Fashion Graph: shoppable products. A system to match outfits to products automatically, and to help people decide what to buy next.
Third step: algorithms
Back when we built recommender systems for music and other products, it was pretty easy. That’s what we think now; we obviously didn’t think that at the time. First, it was easy to capture that you liked a given song. Then, it was easy to capture the sequence in which you and others would listen to that song, and therefore you could capture the correlations. With this data, you could do a lot.
However, as we soon found out, fashion has its own challenges. There is not an easy way to match an outfit to a shoppable product: think about most garments in your wardrobe, most likely you won’t find a link to view or buy those garments online, something you can do for many other products you have at home. Another challenge: the industry is not capturing how people describe clothes or outfits, so there is a strong disconnect between many ecommerces and their shoppers.
Now, deep learning brings a new tool to add to other mechanisms, and changes everything. Owning the correct data set allows us to focus on the specific narrow use cases related to outfit recommendations, and to focus on delivering value through the algorithms instead of spending time collecting and cleaning data.
There are more and more researchers working on these areas: Tangseng’s paper on recommending outfits from a personal closet, or how Edgar Simo-Serra defines similarity between images using user-provided metadata.
Why are Google, Amazon and Alibaba getting into outfits? There is a race to capture a $123b market
Outfits are a key asset in the race to capture the $123 billion US apparel market. Data is also the reason many players are taking outfits to the forefront of technology: outfits are a daily habit, and have proven to be great assets to attract and retain shoppers, and capture their data. Many players are introducing a Shop the Look section with outfits from real people: Amazon, Zalando or Google are a few examples.
Google recently introduced a new feature called Style Ideas showing how a “product can be worn in real life”. The same month Amazon launched its Alexa Echo Look to help you with your outfit, and Alibaba’s artificial intelligence personal stylist helped them achieve record sales during Singles Day.
Ten years from now
Some people think that fashion data is in the same place as music data was in 2003: ready to play a very relevant role. The good news is: the daily habit of deciding what to wear will not change. The need to buy new clothes won’t disappear, either.
So, what do you think? Where will we be ten years from now? Will taste data build unique online experiences? What role will outfits play? How will machine learning change fashion ecommerce?
Learn more about Chicisimo
We are a small team of eight, four on product and four engineers. We believe in focusing on our very specific problem; no one on earth can understand the problem better than us. Our thesis: closets will soon be digitized, people will have more control over their clothes, and deciding your outfit will not be a pain. Making people feel great and confident by helping them choose the right outfit, that’s the goal. We also believe in building the complete solution ourselves while doing as few things as possible. We work 100% remote and live in Slack and GitHub.
He estado trabajando en Silicon Valley más 3 años. Del 2005 al 2009, una temporada iba ahí prácticamente cada 2 semanas, otra temporada viví allí. 101 arriba y abajo. Y vuelta a empezar.
Me encantó. Fue una experiencia personal y profesional increíble. Viví la explosión del 2.0 (sí, de eso), conocí muy de cerca los primeros días de Arrington, Twitter, etc. Conocí a mucha gente, viví muchas cosas, fui a muchas fiestas, meetups, reuniones, etc. Recibí muchos “no”, algunos “si”. Me encantó.
Ahora en cambio estoy harto de Silicon Valley. De la adoración ciega que desde aquí se siente por ese sueño. Silicon Valley no es un lugar. Es un estado mental.
Hace unos días Informe Semanal emitía una pieza sobre los 20 años desde la llegada del Ejército español a Bosnia, y uno de los militares entrevistados dijo que lo que más le sorprendió es que, a pesar de la muerte, destrucción y sufrimiento, durante la guerra “la vida sigue”. Los niños van a la escuela, los mayores al supermercado, los jóvenes se divierten…
Yo estuve en la antigua Yugoslavia (Bosnia en 1996, Croacia en 1997), y eso fue lo que más me sorprendió. La vida sigue.
Estuve en Mostar en 1996 como Observador Internacional y Supervisor Electoral de Naciones Unidas, apoyando y supervisando las primeras elecciones democráticas en Bosnia y Hercegovina tras la guerra, durante un mes. Mostar era una ciudad aún en guerra, dividida entre la zona bosnia y la zona croata, edificios destruidos, intercambio de disparos y cañonazos todas las noches, y en la que la calle divisoria estaba siempre desierta, por el riesgo de los francotiradores.
(Plaza de España en Mostar)
La frase del militar “la vida sigue” me trajo muchos recuerdos, y el primero es el de mi llegada a Mostar: al llegar a la ciudad por la noche tras dos días de viaje, vi normalidad en medio de la destrucción. Y fue un contraste tan grande que es uno de mis primeros recuerdos de la experiencia. Abajo escribo, de manera desordenada, algunos recuerdos.
El viaje hasta Mostar fue increible. De Viena fuimos en avión a Sarajevo, e hicimos noche en domicilios particulares, no en hoteles. Llegamos de noche y todo estaba oscuro, pero recuerdo que al día siguiente cuando me desperté y se veía la ciudad, Sarajevo me pareció muy similar a Bilbao. Un botxo, un valle, la ciudad estaba en un valle rodeada de colinas, esto es muy importante para después poder entender el problema de los francotiradores, que yo antes de ir no lo entendía. Otro recuerdo es que en la casa no había agua corriente, sino palanganas y ahí te arreglabas. Otro recuerdo es cómo los edificios estaban agujereados por balazos. No recuerdo ver muchos cañonazos, pero sí muchos pequeños agujeros resultado de ráfagas de metralleta.